Key Takeaways
- Live retrieval helps AI systems answer questions about changing information.
- Reliable results require checks for relevance, freshness, authority, and agreement.
- Better-ranked sources are not always better evidence for a specific answer.
- Citations and logs make outputs easier to inspect, reproduce, and improve.
- Web-connected systems need defenses against misleading content and prompt injection.
AI applications are most useful when they can distinguish durable knowledge from facts that change by the hour. A strong web retrieval layer helps an assistant find, assess, and use current evidence before drafting an answer. Teams evaluating search infrastructure, including Tavily alternatives, should treat retrieval quality as a product requirement rather than a background implementation detail.
Web retrieval is the evidence layer behind many AI chatbots, research products, customer-support tools, coding assistants, and autonomous agents. It can give a model access to release notes, policy updates, schedules, technical documentation, and other information that may not exist in its training data.
What Web Retrieval Means in an AI Application
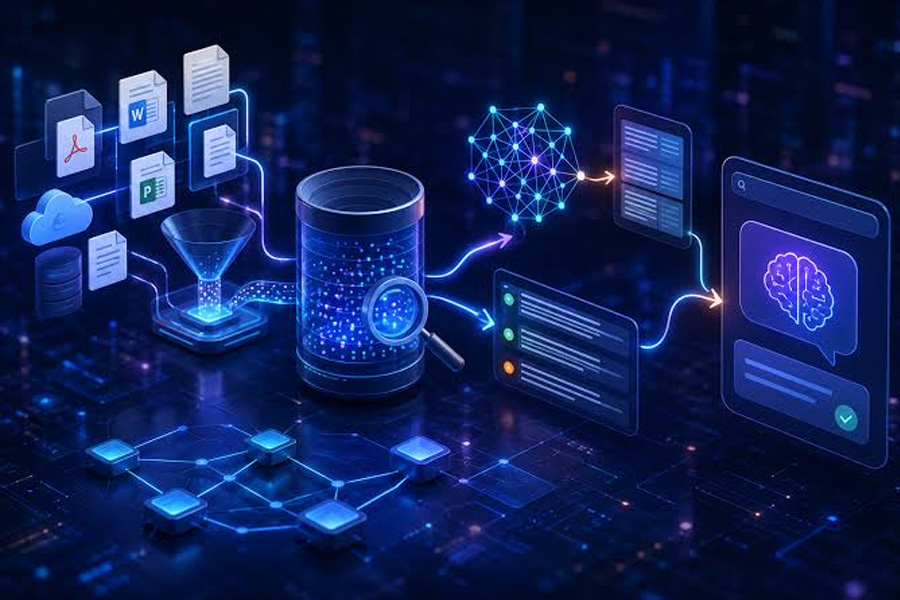
Web retrieval is the process of searching for external information, extracting useful passages, and supplying that evidence to an AI model before it responds. For example, a coding assistant can check a current software release note before suggesting installation steps. This differs from relying only on the model’s built-in knowledge, which may be incomplete or outdated.
Why Model Knowledge Alone Is Not Enough
Regulations, product features, prices, event schedules, public announcements, and security guidance can change after a model has been trained. A response can sound confident while still relying on old information. Retrieval provides the application with new material, but it does not automatically guarantee a correct answer. The system must still select trustworthy evidence and reason carefully from it.
The Four Tests of Reliable Retrieval
Relevance
A useful result addresses the user’s actual intent, not merely a related keyword. The system should identify important details such as product version, country, date range, audience, and requested depth before it searches.
Freshness
Time-sensitive questions need information recent enough for the task. Retrieval logic should consider publication and update dates, especially for product documentation, policies, security notices, and current events.
Authority
The best source depends on the claim. Official documentation is usually the strongest evidence for a product feature, while a government agency, standards body, university, or primary research publisher may be more appropriate for other subjects.
Agreement
For consequential or disputed claims, compare multiple credible sources. If they conflict, the application should surface the uncertainty, explain the difference when possible, or avoid presenting a single conclusion as a settled fact.
Why Search Ranking Is Only One Part of the Process
A high-ranking page may be broad, outdated, thin, or poorly matched to the request. Retrieval systems work better when they evaluate page structure, descriptive headings, publication details, clear ownership, and passage-level meaning. In practice, a focused paragraph that directly answers the question is often more useful than an entire page full of loosely related material.
A Practical Retrieval Pipeline
- Clarify the request: Identify the goal, location, timeframe, and required format.
- Rewrite the query: Turn a vague question into focused search terms.
- Gather sources: Collect enough evidence to compare important claims.
- Extract passages: Remove navigation, ads, repeated copy, and irrelevant sections.
- Rank evidence: Score passages for relevance, freshness, authority, and agreement.
- Generate and cite: Provide the model with selected evidence and connect claims to sources.
- Log the process: Retain queries, timestamps, source details, and outputs for review.
Why Context Quality Affects Answer Quality
Retrieval can fail when the supplied context is weak. Missing qualifiers can turn a narrow rule into a universal claim, old statistics can distort an answer, and unclear source ownership can make promotional copy look authoritative. More context is not always better, either. Large collections of marginally relevant text can bury the key evidence, making it harder for the model to follow the user’s question.
Citations and Traceability Build Trust
A citation should support the specific statement beside it, not function as a decorative list of links at the end. Show a source title, URL, and relevant date when available. Internally, keep retrieval logs so a team can investigate why an answer used a particular source, reproduce a failure, and improve ranking rules or source policies.
Safety Risks in Web-Based AI Systems
External pages are untrusted input. They may include incorrect claims, manipulative instructions, or content designed to steer an agent into unsafe actions. Prompt injection attacks exploit the mixing of untrusted input with higher-trust instructions, so retrieved text should be clearly separated from system rules and tool permissions.
Filter suspicious content, restrict what an agent can do, require confirmation before sensitive actions, and use human review for medical, legal, financial, security, or other high-impact decisions. Retrieval should inform the model, not grant a webpage control over the application.
How to Measure Retrieval Quality
Test with a realistic set of questions, then measure whether the right source appears near the top, whether the answer is accurate, and whether each citation actually supports the statement it accompanies. Track failed searches, empty results, latency, and cost. Include ambiguous prompts, spelling errors, recent changes, and conflicting sources, then review performance by topic instead of trusting one aggregate score.
Web Retrieval Trends
Retrieval is increasingly becoming a context service for agents rather than a simple search box. Systems are placing more emphasis on snippets, dates, source URLs, citations, and governed access. For example, a web search for grounded AI agents can return snippets, source titles, URLs, and publication dates for agent workflows.
Common Questions
Is web retrieval the same as RAG?
Web retrieval can be part of retrieval-augmented generation, or RAG. RAG can also retrieve from private documents, internal databases, and knowledge bases.
Does retrieval stop hallucinations?
No. It can reduce unsupported answers, but poor sources, weak ranking, incomplete context, and flawed reasoning can still produce errors.
How many sources should an application use?
A simple fact may need one authoritative source. A complex, changing, or disputed question may require multiple sources and an explicit note on uncertainty.
Simple Launch Checklist
- Define which questions require live web data.
- Set preferred source types and freshness rules by topic.
- Require evidence for important claims.
- Test low-quality, conflicting, and malicious content.
- Log searches, sources, timestamps, responses, and user feedback.
Reliable web retrieval is not a bolt-on feature. It is a disciplined process of focused search, evidence selection, source evaluation, safe handling of context, citations, and testing. Teams that build those controls into their AI applications can create answers that are more current, reviewable, and useful.